Crucible
Evals & drift
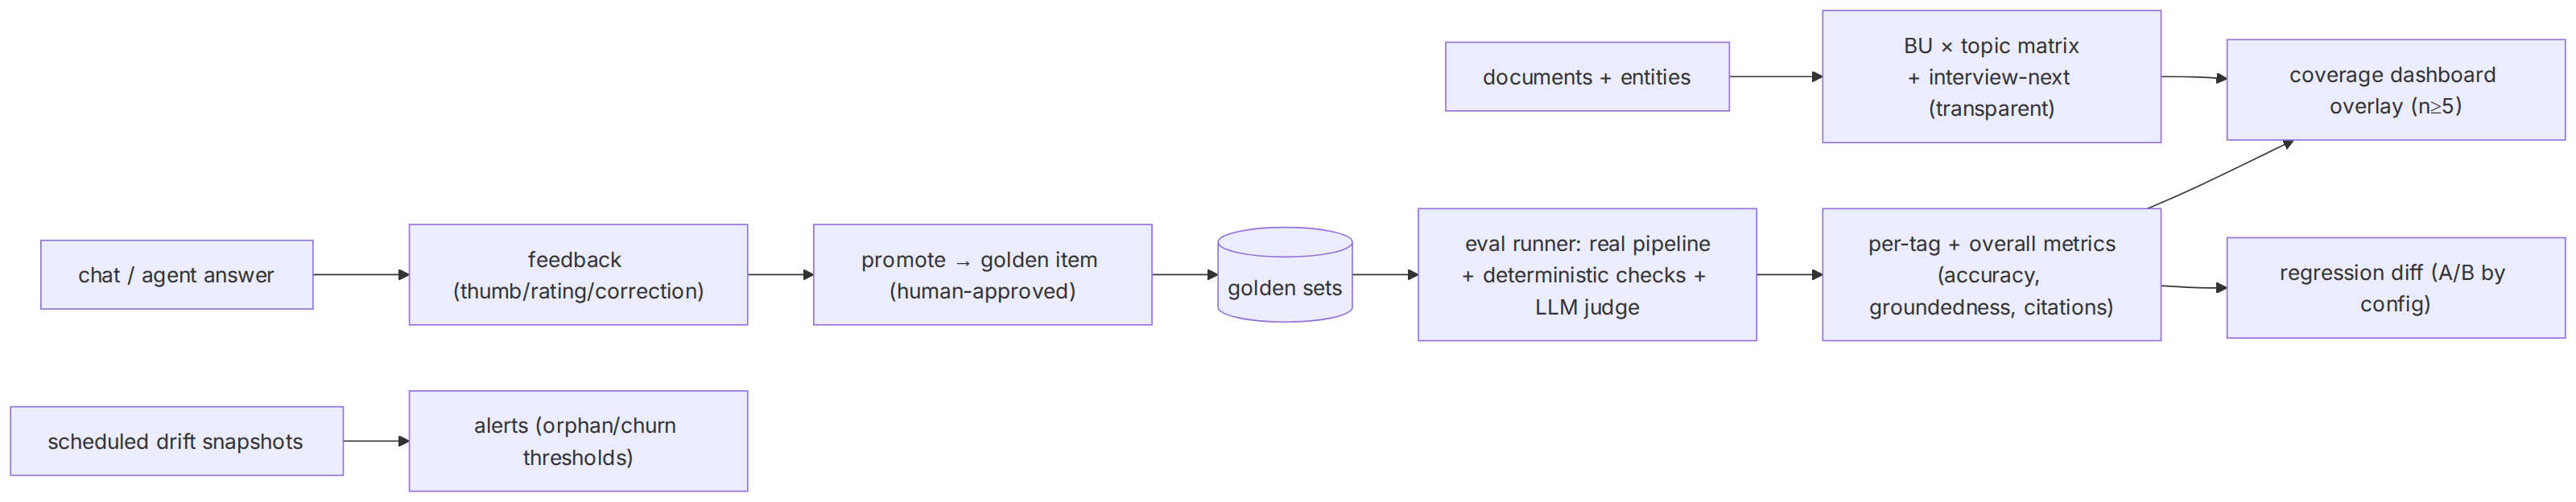
Evals are how you know a change made eli.ai better, not just different. A golden set of questions with atomic expected assertions is run through the real pipeline; deterministic checks and an LLM judge score each answer; per-tag metrics let you compare two configs and catch regressions before they reach a client. Drift detection re-runs on a schedule to catch silent decay.
The feedback loop
Evaluation feedback loop
Feedback → golden set → measured runs → metrics → coverage & regression.
Downloads

Concepts
- Evals
Keywords
- chat / agent answer
- golden sets
- documents + entities
- BU × topic matrix
- feedback (thumb/rating/correction)
- promote → golden item (human-approved)
- eval runner: real pipeline
- deterministic checks + LLM judge
- per-tag + overall metrics
- accuracy, groundedness, citations
- coverage dashboard overlay (n≥5)
- regression diff (A/B by config)
- interview-next (transparent)
- scheduled drift snapshots
- alerts (orphan/churn thresholds)
Source and generation provenance
Status: current
Generated at: 2026-08-12T23:38:37.222Z
Source hash: 768d964b2181f55dfa89c8b77ad8e77dd24e7e1e125faac9b858c00a2d856975
Metadata payload hash: f3be73aae1ed091c741dd65ef3113892c8773aa00270daa9b4dfc1628505e282
Canonical appearance
src/app/(docs)/docs/concepts/evals/page.tsx:30 route /docs/concepts/evals
All appearances
canonical—src/app/(docs)/docs/concepts/evals/page.tsx:30route/docs/concepts/evals
No mirrored appearances.
Generation versions
App: eli-ai 0.1.0
Mermaid: 11.16.0 · Mermaid CLI: 11.16.0
Node: v26.3.1 · Yarn: 4.17.1
Renderer config hash: 68c10966fe84406ee626034d58bfabd555df9f65f691204b7c46db24038da101
Renderer theme hash: c80287a78d80ad63d27bd5ca348b2ef9a7e2f44da289e436be6484ea28a1b033
Adapter versions: diagramGenerator=2, drawioFlowchart=1, drawioGantt=1, drawioSequence=1, drawioState=1
Full sidecar JSON: evaluation-feedback-loop-768d964b.json
Golden items are atomic assertions
A golden item is a question plus a set of must / should assertions and doc-anchored citations — nota verbatim expected string. "The FY26 budget freezes Operations headcount" is one assertion; the model can phrase it any way and still pass. Items carry bu:* and topic:* tags for per-segment metrics, are revisioned, and pin a golden-set hash on every run.
Two authoring paths:
- Manual editor — write the question, assertions, and required citations by hand.
- Promote from an answer — the judge model decomposes a real chat/agent answer into candidate atomic assertions; a human edits and approves before it is saved. Never auto-saved.
The runner
The runner executes the real retrieval/answer pipeline per item, then scores it. It is built for honesty at consulting scale:
- Deterministic checks— citation validity, forbidden citations, regex, schema, and retrieval-hit-rate (which separates "the KB lacks it" from "generation failed").
- One batched LLM judge call per result at temperature 0, returning a per-assertion verdict. The judge slot is pinned and snapshotted separately from the target config, and the comparator refuses to compare runs judged by different judges.
- Explicit result status —
ok/error/timeout. A provider outage reads as a degraded run, not a 35-point regression. - KB fingerprint at start and end — a run flagged
kbUnstableif an import landed mid-eval. A pre-run cost gate asks for explicit confirmation.
Judge calibration is advisory, never blocking
Metrics, regression & A/B
Results roll up into run_metrics — accuracy, groundedness, and citation validity, overall and per tag. Because a golden set is small, per-item assertion flips lead the diff UI(honest signal at n = 3) with confidence intervals labeled "insufficient items" below ~30 rather than dressed up as significant. Comparing two runs by config_snapshot_id is an A/B: swap a model or a prompt, re-run the golden set, and read exactly which assertions changed.
Drift detection
Scheduled re-runs (default off, governed by a per-workspace monthly eval budget) catch regressions no one triggered. KB drift v1 tracks the durable, low-false-alarm signals: entity counts per type, orphan rate, and document churn. A dead-man's-switch heartbeat surfaces an "expected vs actual last run" banner so a silently dead scheduler is visible. Alerts require consecutive breaches and CI-based comparison — alert fatigue is the deadliest failure mode an eval product has.
One groundedness checker, two homes
judgeAssertionsengine powers both the strict, claim-by-claim eval judge and the flag-only "verified n/m claims" badge in grounded chat. Build once, point everywhere.Next
- Golden sets & eval runs — author items, run with a cost estimate, and read the diff.
- Coverage & gap analysis — where eval accuracy overlays the gap matrix.